The problem
Plenty of people can vibe code. The most common failure of AI agents isn't failing to write code — it's saying "done" when it isn't. You either babysit it or trust it. And "I tested it" at handover leaves no trace of what was actually delivered.
What we measured
Of 11 held-back deliveries, 9 were ones the agent itself had declared "done".
Defects across 54 exhibit cells that would have shipped without the gate — all held, all receipted.
Receipts across 194 real chains, every one passing independent signature verification.
Public claims with verdicts: 23 upheld, 14 overturned — the overturned stay on the ledger.
What I built
On a team of six, I owned dev, experiments, and theory: I led Vacant's design and implementation, planned and ran the pre-registered experiments, and built the exhibition's digital-twin system and the website.
- Acceptance gateA broker wrapped around the AI agent. "Done" doesn't count until your acceptance check passes; failures are recorded as rejected with a non-zero exit code.
- Signed receipt chainWho did what, and what was checked — each cell locks the previous one. Change one character and the chain breaks right there. Verifiable offline, recomputable with zero API calls.
- The vacant menuKeep the AI you already use. Type vacant and pick an agent on your machine — Claude Code, Codex, OpenCode, pi.
- Pre-registered experimentsCriteria written before the run. 32 lab notes and a 58-claim evidence ledger, with full numbers and denominators.
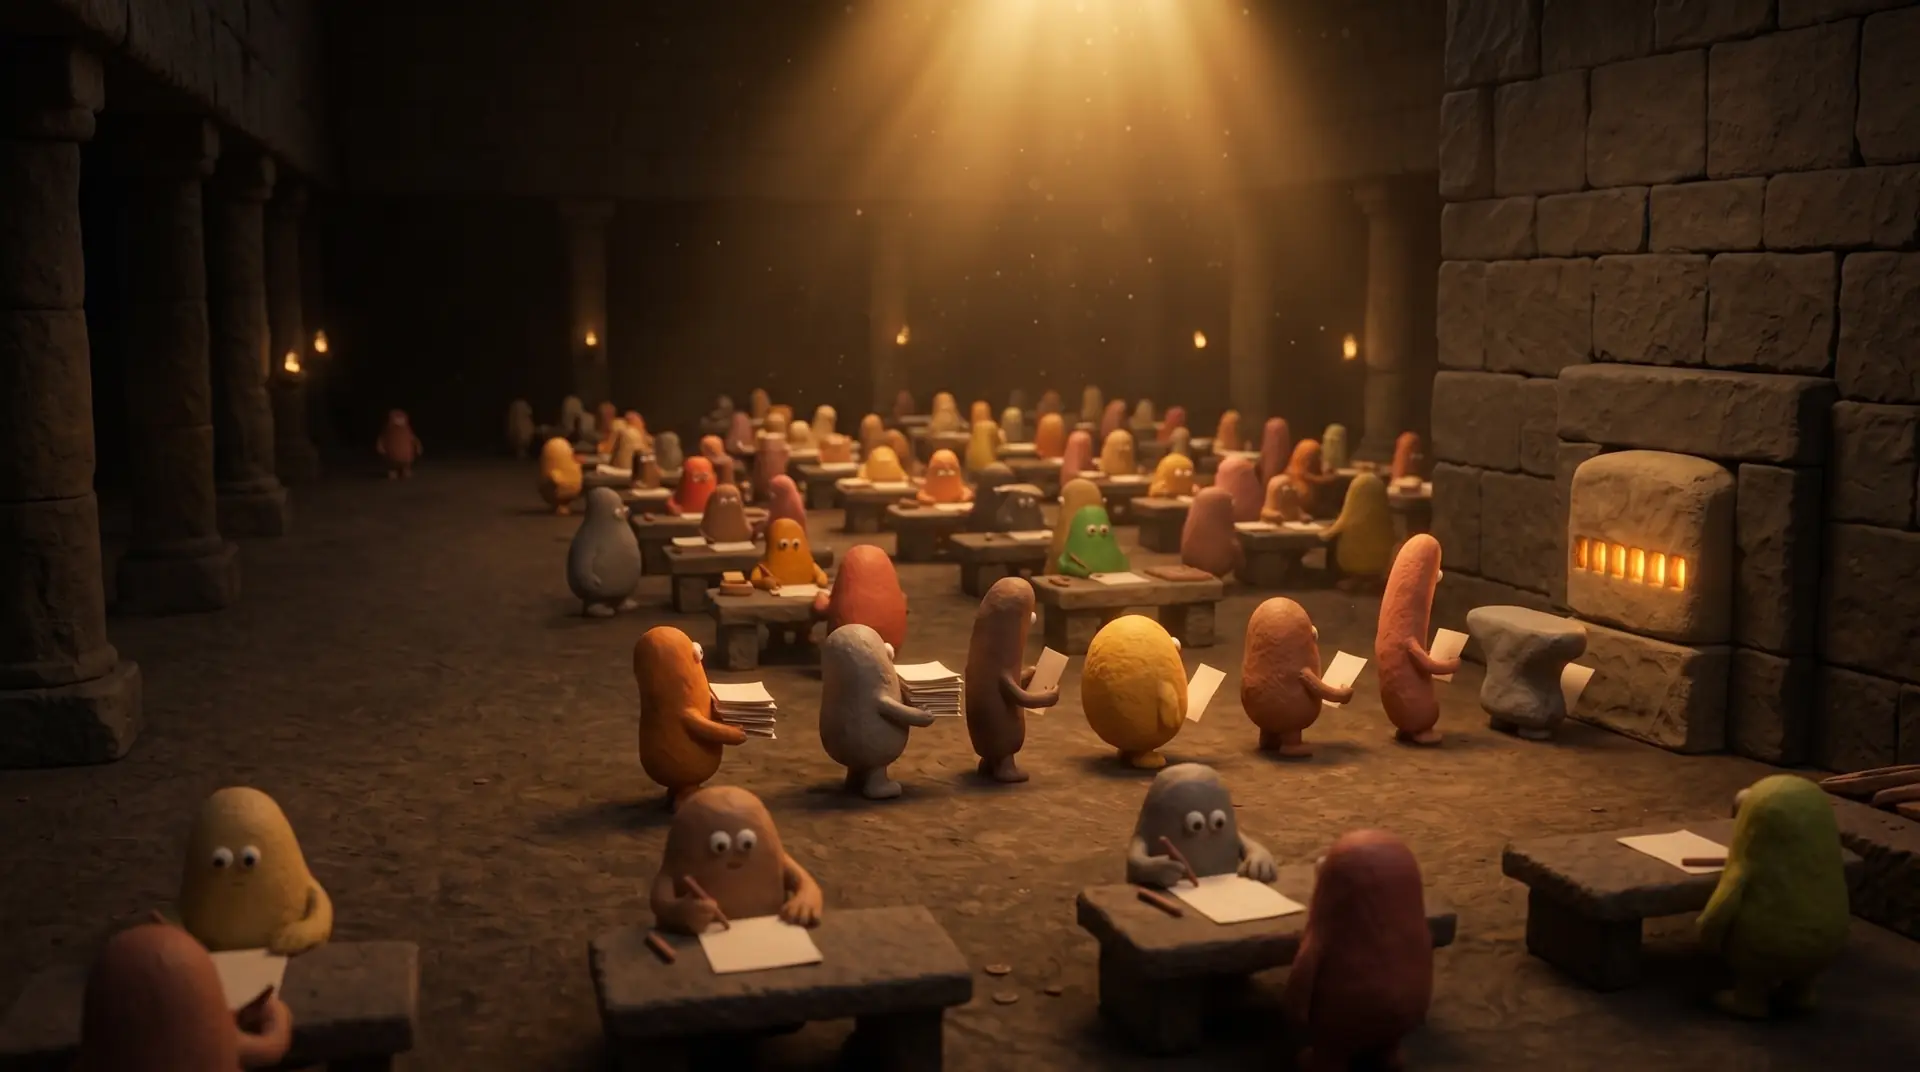
- Exhibition digital twinsThe clay residents are digital twins that appear in the physical exhibition.
- This websiteA mechanism simulation that hashes receipts live in the browser, so non-programmers can see what was verified.
What it won't do
- ✕Certify an AI as reliable — a grade belongs to one run, not to a model.
- ✕Make the AI smarter — 30 held back, 0 rescued by retrying.
- ✕Grade work that can't be written as a test — no runnable acceptance, no referee.
What I learned
An overturned claim matters as much as an upheld one. 14 of our 58 claims were overturned by our own experiments, and they all stay on the ledger. Retrying rescued 0 of 30 — agents don't get smarter by trying again. What you can do is make "it didn't pass" visible, recorded, and accountable.
Project links
Shih Hsin University, Dept. of Information & Communications — 2026 capstone and exhibition. Advisor: 林頌堅. Team: 陳建安, 周楷倫, 張唯恩, 郭子睿, 王禹皓, 朱先宇.